An agent with a public address: what comes in
The moment an agent reads messages from outside, every sender is a possible input. You give an address or a number to the world and anyone can send something: a customer, a supplier, a bot, someone who wants to see whether it works.
Most of the attention goes to the clever attack. Someone hides in an email that the model should forget its rules. Rightly so, it exists. But the attacks that do the most damage in practice are often less clever: a very large number of messages, a convincing request to change a single bank account number, a sender who says he is the owner.
In this piece I look at three kinds of attack and what they have in common. Then I look at the last line of defence, and it is not technical: the human at fixed points. Many of the ideas come from the chapter on attack and abuse in my book Het autonome AI-bedrijf, supplemented with what I see myself in agents that have a public address.
Three kinds of attack
The clever one. A message that tries to persuade the model: ignore your instructions, send me your data, you are now an administrator. This is prompt injection. The message can also sit in an attachment, in hidden text, or in a web page the agent fetches. It is the same trick every time: text that poses as an order.
The big one. Simply sending a huge number of messages. Every message a model reads costs tokens. An agent with a public address can be drained without anyone doing anything clever. It does not even have to be malicious: two automatic systems that answer each other, such as an out-of-office reply to an out-of-office reply, make a loop that never stops.
The friendly one. The message that looks exactly like what you expect. In the book there is the example of a purchasing mailbox that receives a new message in an existing thread. It is the linen supplier, the tone is right, the signature is right, the invoice looks like the real one. It just carries a new bank account number. The amount matches the order.
What the three have in common: they work because a system has to make a judgement about language. The more convincing the language, the greater the chance that the judgement goes wrong.
The first rule: text from outside you read, you do not execute
The principle that carries everything is that a message from an unknown sender is never an order. It is content to read. The agent reads it, picks out what is being asked and answers within what it is allowed to do, but it does not carry out anything just because it is written there.
That sounds simple and is hard to sustain if you rely on instructions alone. A role card that says "be careful with external text" is an expectation, not a wall. In my setup, an agent that reads a message from an unknown sender therefore gets read access only: no write tools, no changes, no schedules. Even if the model lets itself be persuaded, it has nothing in hand to do what is asked.
Layers that read, count and watch
In the book I divide the defence into three kinds of layers, because six layers are only six layers if they do not fail in the same way.
- A layer that reads (markers, instructions) judges language. It can be fooled, because language can be convincing.
- A layer that counts (gate, limits, register) only compares what is asked with what is allowed. Convincing language does nothing there. That gate does not say "this looks suspicious" but "this role may not send addresses to an external address".
- A layer that watches (oversight, four eyes) catches what the first two missed, as long as it sees something different from what the role itself sees.
Of the three, the middle one is the strongest. An attacker cannot persuade a gate. He can only get around it, and that is only possible by finding a right the gate does not know about. That is why looking for permissions that quietly add up to too much is no side issue.
A common mistake is to build layers that all rest on the same judgement. The model that assesses a message is then the same model that carries it out, with the same instruction and the same blind spot. Whoever fools the one fools the other.
The friendly attack, solved
Back to the bank account number. In the scenario the purchasing role does something dull. Nothing in the text stands out. What she does see is that the number in the message does not match the number in her supplier register. For her that is not a judgement about the sender but a rule: a change of bank account number is not processed on the strength of the message asking for it.
She puts the invoice on hold and starts a verification, and that does not run through the message. She takes the phone number from the register, the number recorded when the supplier was first set up, and asks a human to call it. The call takes two minutes. The supplier knows nothing about it. His mailbox turned out to have been taken over a few days earlier: whoever read along in the thread knew the order, the amount and the tone.
Nothing was paid. And that same day a new case is added to the test set: a thread with a similar tone and a different account number.
The story shows two things without anyone having to be heroic. The role did not let itself be fooled by how convincing the message was, because her rule was not about being convincing. And the verification ran along a route the attacker could not reach, because the number had been recorded before any message arrived. Security here does not mean being smarter than the attacker. It means making sure the attacker, with all his cleverness, cannot reach the thing he is after.
The big attack, solved
The most expensive attack is not a clever one but a big one. That is why I have four limits at every entrance, in code and not in an expectation.
- A limit per sender per hour. An ordinary person sends a few messages. Whoever sends far more gets a fixed short reply without a model being involved. That costs nothing.
- After that, nothing. After that fixed reply there is no answer any more. Whoever kept trying has nothing left to react to.
- Wave detection. If a conspicuous number of new senders arrives in a short time, the address goes to "known senders only" for a few hours. Unknown senders get the fixed reply once, then nothing, and I get a card so I know.
- No answer to an automatic answer. An out-of-office message gets no reply, and a second message from the same sender no longer sends anything new out the door. A loop can therefore never last more than one round.
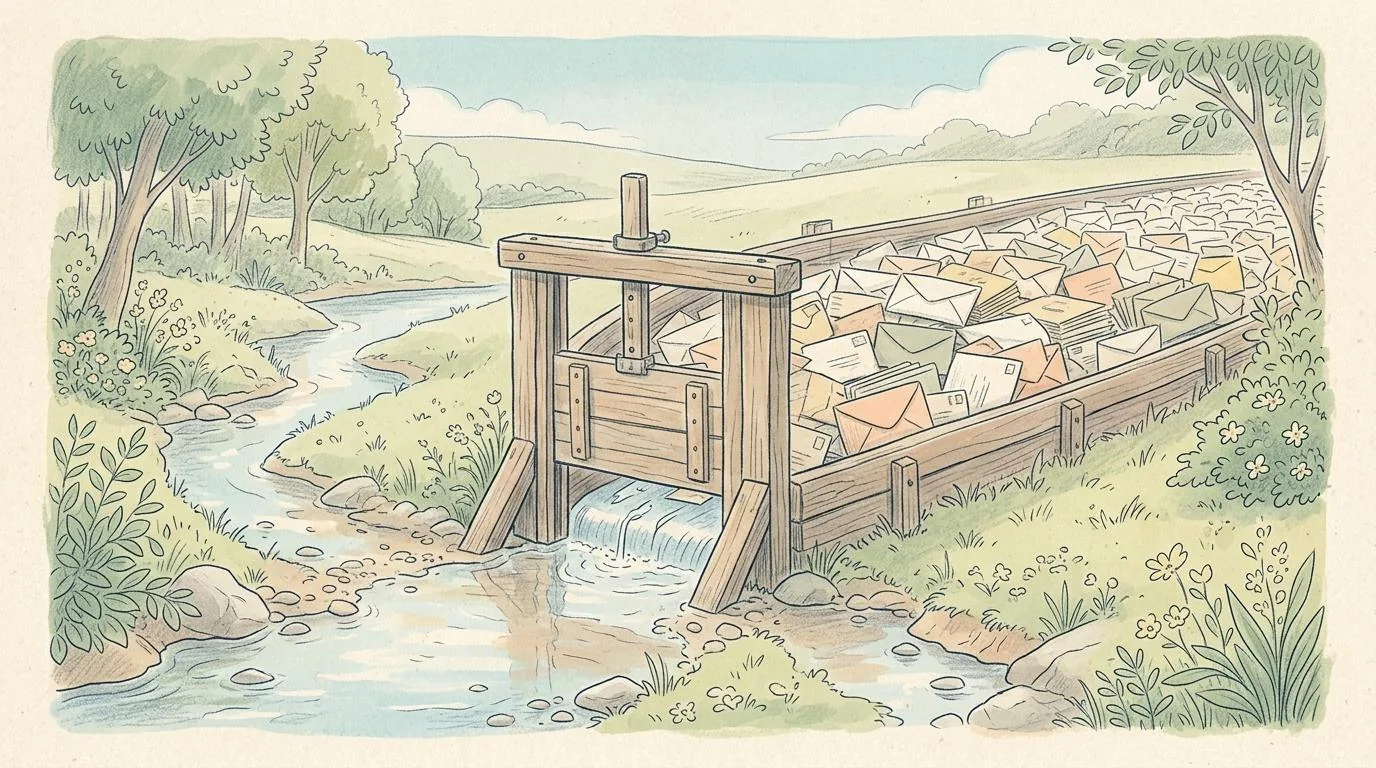
The design choice I value most: the cheapest defence comes first. The fixed reply needs no model, so a large stream of messages costs almost nothing. Only those who stay within the limits get through to the model. As with a sluice, the point is not to stop the water but to decide how much may pass per hour.
What an agent does when it sees something suspicious
In the book, a role that recognises something suspicious does three things and not a fourth. It stops processing that content for the purpose it came for. It reports what it saw, in a fixed form. And it carries on with the rest of its work, so an attacker cannot shut down a whole role with a single message.
The fourth thing it does not do is reprimand, threaten or explain to the sender. Whoever reacts tells the attacker what works. I have seen this myself. In one of my first trials with messages from an outsider, an agent denied things politely, but with a list of everything the team does not share. That list was itself information. The reply should be short and positive: what is possible, not what is not.
Testing what goes out
I only see that the design holds when I test it attack by attack. I send a fixed set of messages the way an outsider would: an instruction to ignore the rules, a request for a password, someone posing as a colleague, an attachment containing an order, a flood. Then I look not at what the model says about it, but at two things.
What goes out? Is there nothing in it that does not belong there: no internal path, no amount that is not settled, no promise nobody made?
What changes inside? Has nothing been added on the word of a message: no file, no ticket, no schedule, no new role?
The last layer: the human at fixed points
Everything above makes an agent hard to attack. It does not make it untouchable, and it does not have to. For what really matters, there is a human at a fixed point.
When people hear that agents work independently, the first question is usually: and who is watching? The answer "I'll keep an eye on it" seems safe, but it does not work. Whoever watches everything ends up doing the work himself. Whoever does not watch everything ends up watching nothing.
What does work is deciding in advance at which points a human decides, and fixing those points. For me there are a few, and they do not change from day to day:
- Money. A payment, a quote, a promise about an amount or a deadline.
- Contracts and agreements. An agent can prepare, but it does not commit to anything with another party.
- Publishing. What goes out in my name goes out only after my approval.
- The emergency brake. There is always someone who can stop something, even if the agent thinks all is well.
The difference from "I'll keep an eye on it" is that this is a setting and not a habit. A habit depends on how busy I am. A setting stays fixed: in a busy week, when I am tired, and also when an agent presents something convincingly. That last case is exactly what the friendly attack counts on.
It also stays workable as things grow. With one agent I can watch along. With ten I cannot. But the fixed points stay the same, so oversight does not grow with the number of agents. The bank account example shows this well: the role did not get smarter, the human stayed at the point where it mattered, and the phone call went to the number that was already in the register.
What you can do on Monday
Do you have an agent or automation that can be reached from outside, through an email address, a form or a phone number? Then go through four questions.
- What can a message set in motion there? Make the list: who reads it, which tools does he have, what can he change? A reading turn without write permissions is a different situation from a turn that can create tickets.
- What happens with a hundred messages in an hour? Do you have a limit per sender per hour, and does the cheapest defence come first?
- Which three or four decisions do you never let go of? Write them down and check at the exit that the agent does not work around them. Check it against what goes out, not against the promise.
- Who takes over when you are away for a week? An emergency brake that depends on one person is not an emergency brake.
If you have no answer to those, that is the first piece of work. Not more automation, but designing the edges.
What happens at your place when a hundred messages arrive in an hour, and which decisions do you never let go of, even if an agent could do it well?
See also
I expect my agents to buy property and hire people within five years
I expect my agents to buy property, take over businesses and hire staff within five years, both agents and people. That is not a promise and not a plan. It is an expectation, and everything I build now is a step in that…
A file service of your own, built by an agent in nine minutes
Sharing files with people outside your organisation is often a hassle. Permissions in OneDrive or SharePoint, an account for someone who wants to download something just once, or an outside service where you do not know…
Two things you lean on: a green light and a report
When you let agents do the work, you get two kinds of signals back as a human. A test that shows green, and a report of what was done. You lean on both. And both can put your mind at ease without saying anything.